RK3576 / RKNN / YOLO / Pose Estimation に基づく 3D 人体姿勢推定システム
本プロジェクトは GitHub で確認できます: https://github.com/doublelf/3D-Human-Pose-Estimation/tree/main
reComputer RK3576 向けに最適化された YOLOv8 物体検出 + 姿勢推定パイプラインです。本プロジェクトは reComputer AI Lab プラットフォームのベースアルゴリズムに基づき開発されており、推論バックエンドとスケジューリングロジックを置き換えることで、RK3576 のヘテロジニアス計算ユニットに計算タスクを分散します:
| 計算ユニット | 担当タスク |
|---|---|
| NPU 0+1 | YOLOv8n 80 クラス物体検出(モデルファイル yolov8n.rknn) |
| NPU 2 | YOLOv8n-pose 17 キーポイント姿勢推定(モデルファイル yolov8n_pose.rknn) |
| VPU | ffmpeg h264_rkmpp による H.264 ハードウェアコーデック |
| CPU | Letterbox 前処理、DFL/NMS 後処理、フレーム描画 |
リポジトリ構成
ceshi_rk3576/
├── README.md
├── pyproject.toml
├── requirements.txt
├── Dockerfile
├── configs/
│   └── default.yaml
├── data/
│   ├── inputs/                # 入力動画ソース
│   ├── outputs/               # 結果の出力ディレクトリ
│   └── weights/               # モデル重み: yolov8n.rknn、yolov8n_pose.rknn
├── src/poseball/
│   ├── __init__.py
│   ├── __main__.py
│   ├── cli.py                 # コマンドラインエントリポイント
│   ├── config.py              # YAML ベースの設定管理
│   ├── rknn_engine.py         # NPU 推論ラッパー
│   ├── vpu_codec.py           # ffmpeg サブプロセスによる VPU コーデック
│   ├── models.py              # 便利なモデルローダー
│   ├── preprocess.py          # Letterbox 処理 + BGR→RGB 変換
│   ├── postprocess.py         # DFL/NMS + Letterbox 座標復元
│   ├── video.py               # VPU / cv2 動画読み書きモジュール
│   ├── hw_scheduler.py        # マルチスレッドパイプラインスケジューラ (CPU/NPU/VPU)
│   ├── pipeline.py            # ハイレベル業務オーケストレーション
│   ├── geometry.py            # Point / Rect / Detection データクラス
│   ├── io_utils.py            # JSON およびファイルシステムユーティリティ
│   └── _compat.py             # NumPy 互換性アダプタ層
├── src/py_utils/
│   ├── __init__.py
│   ├── yolov8_utils.py        # 物体検出後処理(ballo プロジェクト由来)
│   └── pose_utils.py          # 姿勢推定後処理(ball プロジェクト由来)
└── tests/
    ├── test_rknn_engine.py
    ├── test_vpu_codec.py
    ├── test_postprocess.py
    └── test_hw_scheduler.py
reComputer RK3576 へのインストール
オプション 1: GitHub からインストール
プロジェクトの取得
git clone https://github.com/doublelf/3D-Human-Pose-Estimation.git && cd 3D-Human-Pose-Estimation環境のセットアップ
# 1. 仮想環境を作成する
python3 -m venv venv
source venv/bin/activate

# 2. 本プロジェクトのパッケージと必要な依存関係をインストールする
pip install -e .
pip install -r requirements.txt

# 3. 対応する Python バージョンの rknn-toolkit-lite2 をインストールする(aarch64 のみ対応)
cd RKNN-Toolkit/
pip3 install rknn_toolkit_lite2-2.3.2-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl
使用方法
# ハードウェアの完全な診断を実行する(新しいデバイスの初回使用時に推奨)
ceshi_rk3576 doctor

# 検出されたハードウェア機能情報を出力する
ceshi_rk3576 info

# 単一フレームのスモークテスト
ceshi_rk3576 smoke --input data/inputs/sample.mp4

# 単一カメラのエンドツーエンドパイプライン(物体検出 + 姿勢推定 + ボール検出)
ceshi_rk3576 infer \
    --config configs/default.yaml \
    --input  data/inputs/sample.mp4 \
    --output data/outputs/annotated.mp4 \
    --json   data/outputs/detections.json

# デュアルカメラパイプライン(主テスト用コマンド)
ceshi_rk3576 dual-infer \
    --input-a  data/inputs/sample-a.mp4 \
    --input-b  data/inputs/sample-b.mp4 \
    --output-a data/outputs/annotated-a.mp4 \
    --output-b data/outputs/annotated-b.mp4 \
    --json-a   data/outputs/detections-a.json \
    --json-b   data/outputs/detections-b.json

# JSON 結果を基に matplotlib で擬似 3D アニメーション MP4 を生成する
ceshi_rk3576 render \
    --json-a     data/outputs/detections-a.json \
    --output     data/outputs/3d.mp4 \
    --depth-mode lr
オプション 2: Docker を使用したインストール
プロジェクトの取得 + ワンクリック実行
イメージのプル
sudo docker pull ghcr.io/doublelf/3d_human_pose_estimation:v1.0デュアルカメラパイプラインの実行
sudo docker run --rm --privileged --net=host   -e PYTHONUNBUFFERED=1 \
  --device /dev/video1:/dev/video1 \
  --device /dev/dri/renderD129:/dev/dri/renderD129 \
  -v /proc/device-tree/compatible:/proc/device-tree/compatible \
  -v $(pwd)/data/inputs:/app/data/inputs \
  -v $(pwd)/data/weights:/app/data/weights \
  -v $(pwd)/data/outputs:/app/data/outputs \
  -v $(pwd)/configs:/app/configs \
  ghcr.io/doublelf/3d_human_pose_estimation:v1.0 \
  ceshi_rk3576 dual-infer --input-a  data/inputs/sample-a.mp4 --input-b  data/inputs/sample-b.mp4 --output-a data/outputs/annotated-a.mp4 --output-b data/outputs/annotated-b.mp4 --json-a   data/outputs/detections-a.json --json-b   data/outputs/detections-b.json
JSON 結果を基に matplotlib で擬似 3D アニメーション MP4 を生成する
sudo docker run --rm --privileged --net=host   -e PYTHONUNBUFFERED=1 \
  --device /dev/video1:/dev/video1 \
  --device /dev/dri/renderD129:/dev/dri/renderD129 \
  -v /proc/device-tree/compatible:/proc/device-tree/compatible \
  -v $(pwd)/data/inputs:/app/data/inputs \
  -v $(pwd)/data/weights:/app/data/weights \
  -v $(pwd)/data/outputs:/app/data/outputs \
  -v $(pwd)/configs:/app/configs \
  ghcr.io/doublelf/3d_human_pose_estimation:v1.0 \
  ceshi_rk3576 render --json-a data/outputs/detections-a.json --output data/outputs/3d.mp4 --depth-mode lr
出力ファイルの説明
| ファイル | 内容 |
|---|---|
annotated*.mp4 | 元のフレーム + バウンディングボックス + 17 キーポイント骨格 + スポーツボールの赤い丸 (COCO クラス 32) |
detections*.json | フレーム単位のデータ: 80 クラスすべての COCO 検出結果 detections、信頼度付き bbox + 17 キーポイント poses、最も良いボール bbox の中心点 ball_xy |
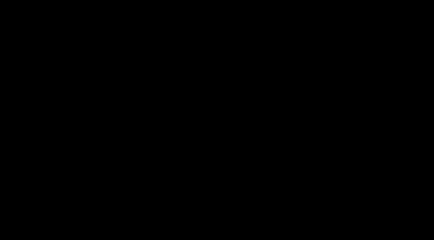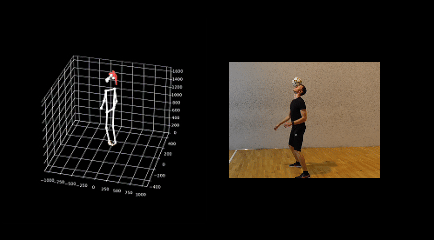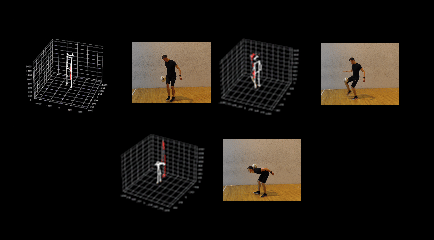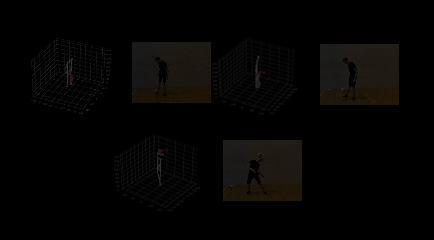
3d.mp4 | matplotlib でレンダリングされた擬似 3D 骨格 + ボールの軌跡 + 左右の足首の軌跡、各フレームごとに回転 (depth_mode=lr);カメラ A のデータのみをレンダリング |
render コマンドは infer または dual-infer で生成された JSON ファイルを読み取ります。2 つのステージは独立しているため、NPU 上で動画を再処理することなく、出力サイズ、フレームレート、または深度モードを調整するために render を再実行できます。
ハードウェアタスク分散
RK3576 NPU トポロジー
RK3576 SoC には 2 つだけの NPU コア(コア 0 とコア 1)があります。同じハードウェアリソースを奪い合わないように、それぞれのモデルが異なるコアにピン留めされ、並列に実行されます:
| モデル | デフォルトの core_mask 設定 | 物理コア |
|---|---|---|
| YOLOv8n 検出器 | NPU_CORE_0 (0x01) | コア 0 |
| YOLOv8n 姿勢モデル | NPU_CORE_1 (0x02) | コア 1 |
これまでのデフォルト設定(検出器に NPU_CORE_0_1、姿勢モデルに NPU_CORE_2)は誤りでした: RKNN ドライバはロード時に NPU_CORE_2 を NPU_CORE_0 に黙って再マッピングし、警告を出力します。この設定では 2 つのモデルがコア 0+1 のリソースを奪い合うことになります。