Fall Detection Project Based on RK3576 / RKNN / YOLO / Pose Estimation
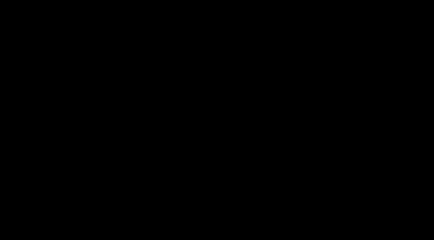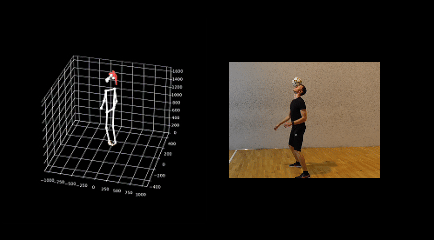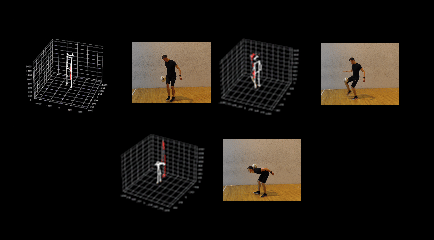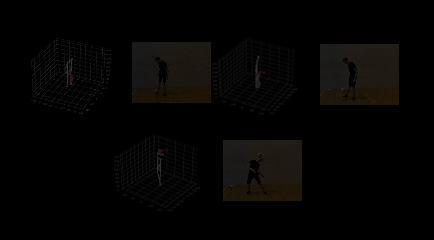
You can view the source code of this project on GitHub: https://github.com/doublelf/3D-Human-Pose-Estimation/tree/main
A YOLOv8 object detection + pose estimation pipeline optimized for the reComputer RK3576. This project is built upon the base algorithms from the reComputer AI Lab platform, replacing the original inference backend and scheduling logic to distribute computational tasks across the RK3576's heterogeneous compute units:
| Compute Unit | Tasks |
|---|---|
| NPU 0+1 | YOLOv8n 80‑class object detection (model file yolov8n.rknn) |
| NPU 2 | YOLOv8n‑pose 17‑keypoint pose estimation (model file yolov8n_pose.rknn) |
| VPU | H.264 hardware codec via ffmpeg h264_rkmpp |
| CPU | Letterbox preprocessing, DFL/NMS post‑processing, and frame rendering |
Repository layout
ceshi_rk3576/
├── README.md
├── pyproject.toml
├── requirements.txt
├── Dockerfile
├── configs/
│   └── default.yaml
├── data/
│   ├── inputs/                # Input video sources
│   ├── outputs/               # Output directory for results
│   └── weights/               # Model weights: yolov8n.rknn, yolov8n_pose.rknn
├── src/poseball/
│   ├── __init__.py
│   ├── __main__.py
│   ├── cli.py                 # Command‑line entry point
│   ├── config.py              # YAML‑based configuration management
│   ├── rknn_engine.py         # NPU inference wrapper
│   ├── vpu_codec.py           # VPU codec via ffmpeg subprocess
│   ├── models.py              # Convenience model loader
│   ├── preprocess.py          # Letterbox handling + BGR to RGB conversion
│   ├── postprocess.py         # DFL/NMS + letterbox coordinate restoration
│   ├── video.py               # VPU / cv2 video read/write module
│   ├── hw_scheduler.py        # Multi‑threaded pipeline scheduler (CPU/NPU/VPU)
│   ├── pipeline.py            # High‑level business orchestration
│   ├── geometry.py            # Point / Rect / Detection data classes
│   ├── io_utils.py            # JSON and file system utilities
│   └── _compat.py             # NumPy compatibility adapter
├── src/py_utils/
│   ├── __init__.py
│   ├── yolov8_utils.py        # Object detection post‑processing (from ballo project)
│   └── pose_utils.py          # Pose estimation post‑processing (from ball project)
└── tests/
    ├── test_rknn_engine.py
    ├── test_vpu_codec.py
    ├── test_postprocess.py
    └── test_hw_scheduler.py
Installation on reComputer RK3576
Option 1: Install from GitHub
Get the project:
git clone https://github.com/doublelf/3D-Human-Pose-Estimation.git && cd 3D-Human-Pose-EstimationSet up the environment:
# 1. Create a virtual environment
python3 -m venv venv
source venv/bin/activate

# 2. Install this package and required dependencies
pip install -e .
pip install -r requirements.txt

# 3. Install the appropriate Python version of rknn‑toolkit‑lite2 (aarch64 only)
cd RKNN-Toolkit/
pip3 install rknn_toolkit_lite2-2.3.2-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl
Usage
# Run a full hardware diagnostic (recommended for first use on a new device)
ceshi_rk3576 doctor

# Print detected hardware capabilities
ceshi_rk3576 info

# Single‑frame smoke test
ceshi_rk3576 smoke --input data/inputs/sample.mp4

# Single‑camera end‑to‑end pipeline (object detection + pose estimation + ball detection)
ceshi_rk3576 infer \
    --config configs/default.yaml \
    --input  data/inputs/sample.mp4 \
    --output data/outputs/annotated.mp4 \
    --json   data/outputs/detections.json

# Dual‑camera pipeline (primary test command)
ceshi_rk3576 dual-infer \
    --input-a  data/inputs/sample-a.mp4 \
    --input-b  data/inputs/sample-b.mp4 \
    --output-a data/outputs/annotated-a.mp4 \
    --output-b data/outputs/annotated-b.mp4 \
    --json-a   data/outputs/detections-a.json \
    --json-b   data/outputs/detections-b.json

# Generate a matplotlib pseudo‑3D animation MP4 from JSON results
ceshi_rk3576 render \
    --json-a     data/outputs/detections-a.json \
    --output     data/outputs/3d.mp4 \
    --depth-mode lr
Option 2: Install Using Docker
Get the project and run with one command.
Pull the Docker image:
sudo docker pull ghcr.io/doublelf/3d_human_pose_estimation:v1.0Run the dual‑camera pipeline:
sudo docker run --rm --privileged --net=host   -e PYTHONUNBUFFERED=1 \
    --device /dev/video1:/dev/video1 \
    --device /dev/dri/renderD129:/dev/dri/renderD129 \
    -v /proc/device-tree/compatible:/proc/device-tree/compatible \
    -v $(pwd)/data/inputs:/app/data/inputs \
    -v $(pwd)/data/weights:/app/data/weights \
    -v $(pwd)/data/outputs:/app/data/outputs \
    -v $(pwd)/configs:/app/configs \
    ghcr.io/doublelf/3d_human_pose_estimation:v1.0 \
    ceshi_rk3576 dual-infer --input-a  data/inputs/sample-a.mp4 --input-b  data/inputs/sample-b.mp4 --output-a data/outputs/annotated-a.mp4 --output-b data/outputs/annotated-b.mp4 --json-a   data/outputs/detections-a.json --json-b   data/outputs/detections-b.json
Generate the matplotlib pseudo‑3D animation MP4 from JSON results:
sudo docker run --rm --privileged --net=host   -e PYTHONUNBUFFERED=1 \
    --device /dev/video1:/dev/video1 \
    --device /dev/dri/renderD129:/dev/dri/renderD129 \
    -v /proc/device-tree/compatible:/proc/device-tree/compatible \
    -v $(pwd)/data/inputs:/app/data/inputs \
    -v $(pwd)/data/weights:/app/data/weights \
    -v $(pwd)/data/outputs:/app/data/outputs \
    -v $(pwd)/configs:/app/configs \
    ghcr.io/doublelf/3d_human_pose_estimation:v1.0 \
    ceshi_rk3576 render --json-a data/outputs/detections-a.json --output data/outputs/3d.mp4 --depth-mode lr
Output File Description
| File | Contents |
|---|---|
annotated*.mp4 | Original frames + bounding boxes + 17-keypoint skeleton + red circle for the sports ball (COCO class 32) |
detections*.json | Per-frame detections (all 80 COCO classes), poses (bbox + 17 keypoints with confidences), ball_xy (centred on the best sports-ball bbox) |
3d.mp4 | matplotlib pseudo-3D skeleton + ball trail + left/right ankle trails, rotating each frame (depth_mode=lr); renders camera A only |
The render command reads JSON files produced by either infer or
dual-infer, so the two stages are independent: re-run render
afterwards to tweak out_size, fps, or depth_mode without
re-processing the videos on the NPU.
Hardware task distribution
RK3576 NPU topology
The RK3576 SoC has only two NPU cores (cores 0 and 1). We pin each model to a distinct core so they can run concurrently without contending for the same hardware:
| Model | Default core_mask | Physical core |
|---|---|---|
| YOLOv8n detector | NPU_CORE_0 (0x01) | Core 0 |
| YOLOv8n-pose | NPU_CORE_1 (0x02) | Core 1 |
The previous default of NPU_CORE_0_1 for the detector and
NPU_CORE_2 for the pose model was wrong: the RKNN driver silently
remaps NPU_CORE_2 to NPU_CORE_0 and warns at load time. That
configuration would have both models fighting for cores 0+1.