This project combines shelf vision, inventory state, voice interaction, and sales-conversation analysis in one browser interface running on reComputer RK3588. It connects to reCamera and ReSpeaker XVF3800 and performs RKNN visual inference, speech recognition, speaker separation, local language-model processing, and text-to-speech at the edge.
After the runtime assets are prepared, video, audio, inventory data, and generated results remain local. No cloud API is required while the demonstration is running.
Source code: https://github.com/Seeed-Projects/Lab-Prooject-RK
Highlights
- One Vue frontend and one FastAPI service manage three demonstration experiences.
- RKNN object detection runs on the RK3588 NPU.
- reCamera supplies detected video and live product state.
- ReSpeaker XVF3800 provides far-field audio capture.
- Local Qwen3-ASR, speaker separation, RKLLM, and Piper TTS handle voice workflows.
- The interface shows hardware, model-service, and inference-pipeline status.
- Inventory quantities come from deterministic business logic instead of LLM guesses.
Three demo experiences
1. Single-camera smart shelf and voice assistant
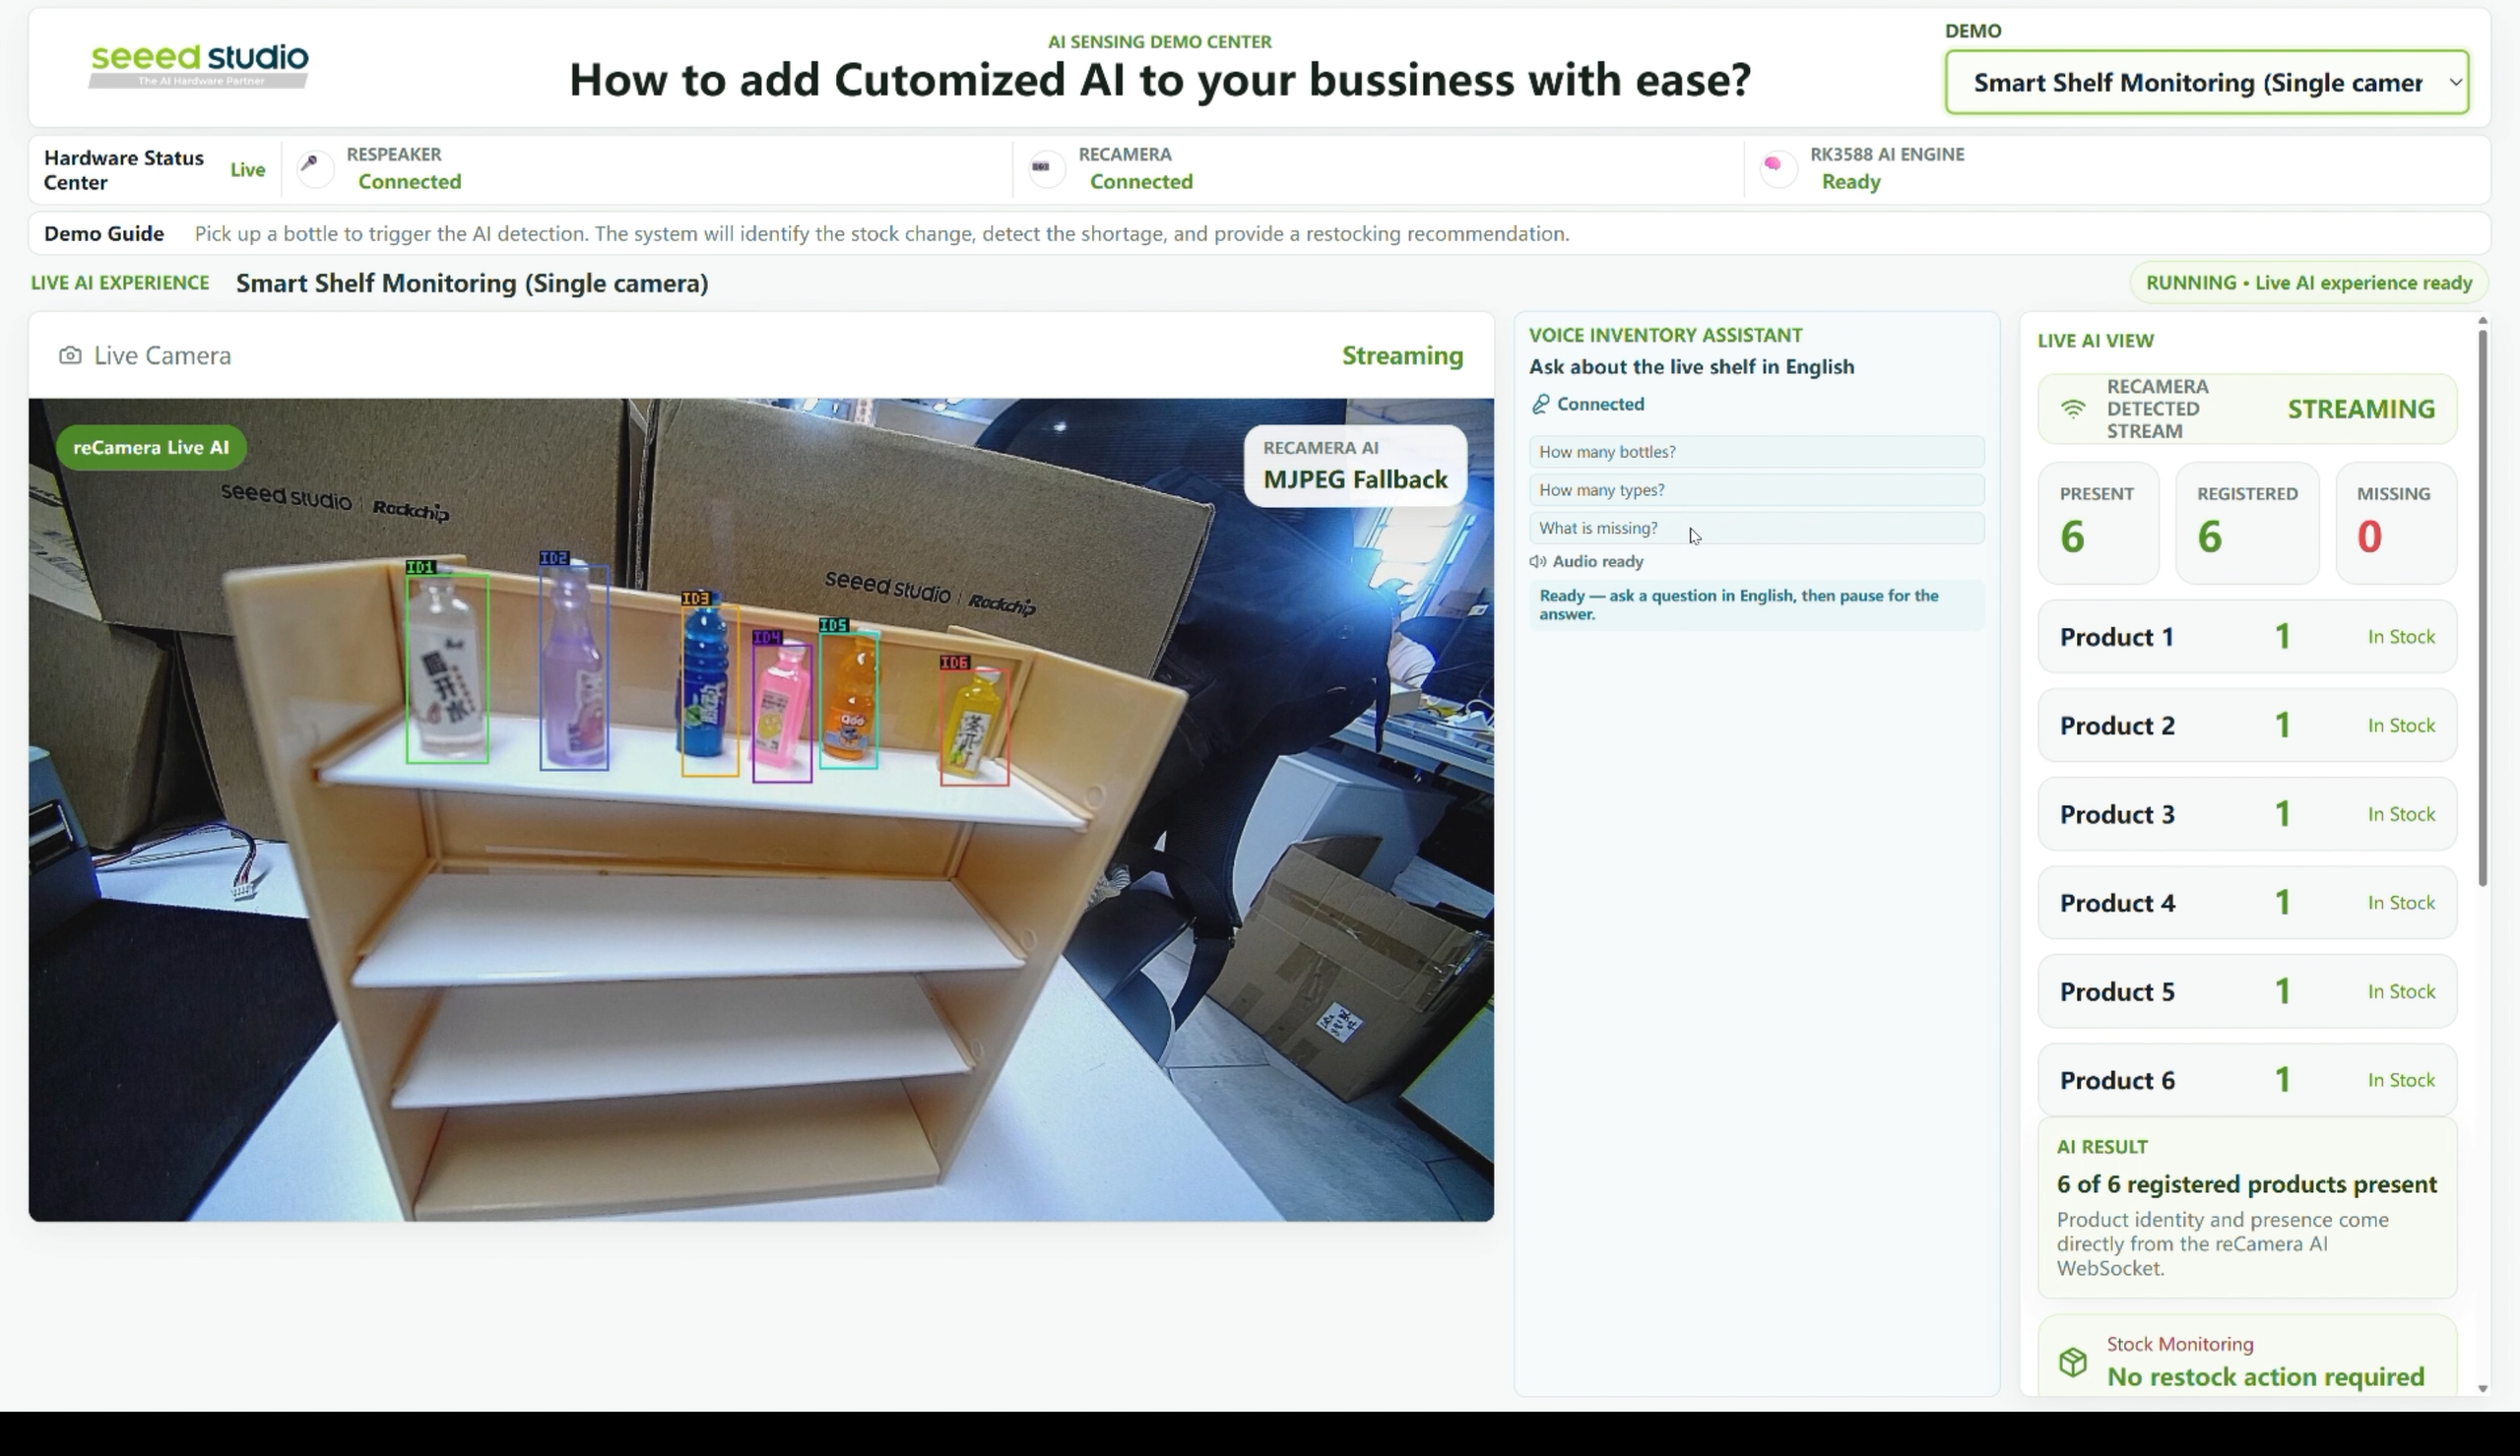
reCamera sends an annotated RTSP stream and current product state to the reComputer. Staff can ask questions such as:
- How many bottles remain on the shelf?
- How many product types are present?
- Which products are missing?
The answer appears as structured data in the browser and can be spoken through the attached speaker.
The LLM identifies the user's intent only. Product names and quantities are calculated by the application from a recent reCamera state. If that state is missing or stale, the application says that inventory is unavailable instead of producing an unverified count.
2. Four-stream smart-shelf monitoring
Four independent capture and inference workers run concurrently on the RK3588. The dashboard shows:
- four annotated video streams;
- capture, inference, and display rates for each stream;
- NPU worker status;
- a shared restocking-event timeline; and
- shelf-state changes and restocking alerts.
The repository includes two FP16 RKNN models, the RKNN Lite 2.3.2 arm64 wheel, a sample video, and the demo configuration.
The shelf regions and event rules are configured for the included sample video. Recalibrate the ROIs and business rules when using a different camera position or shelf layout.
3. Sales conversation analysis
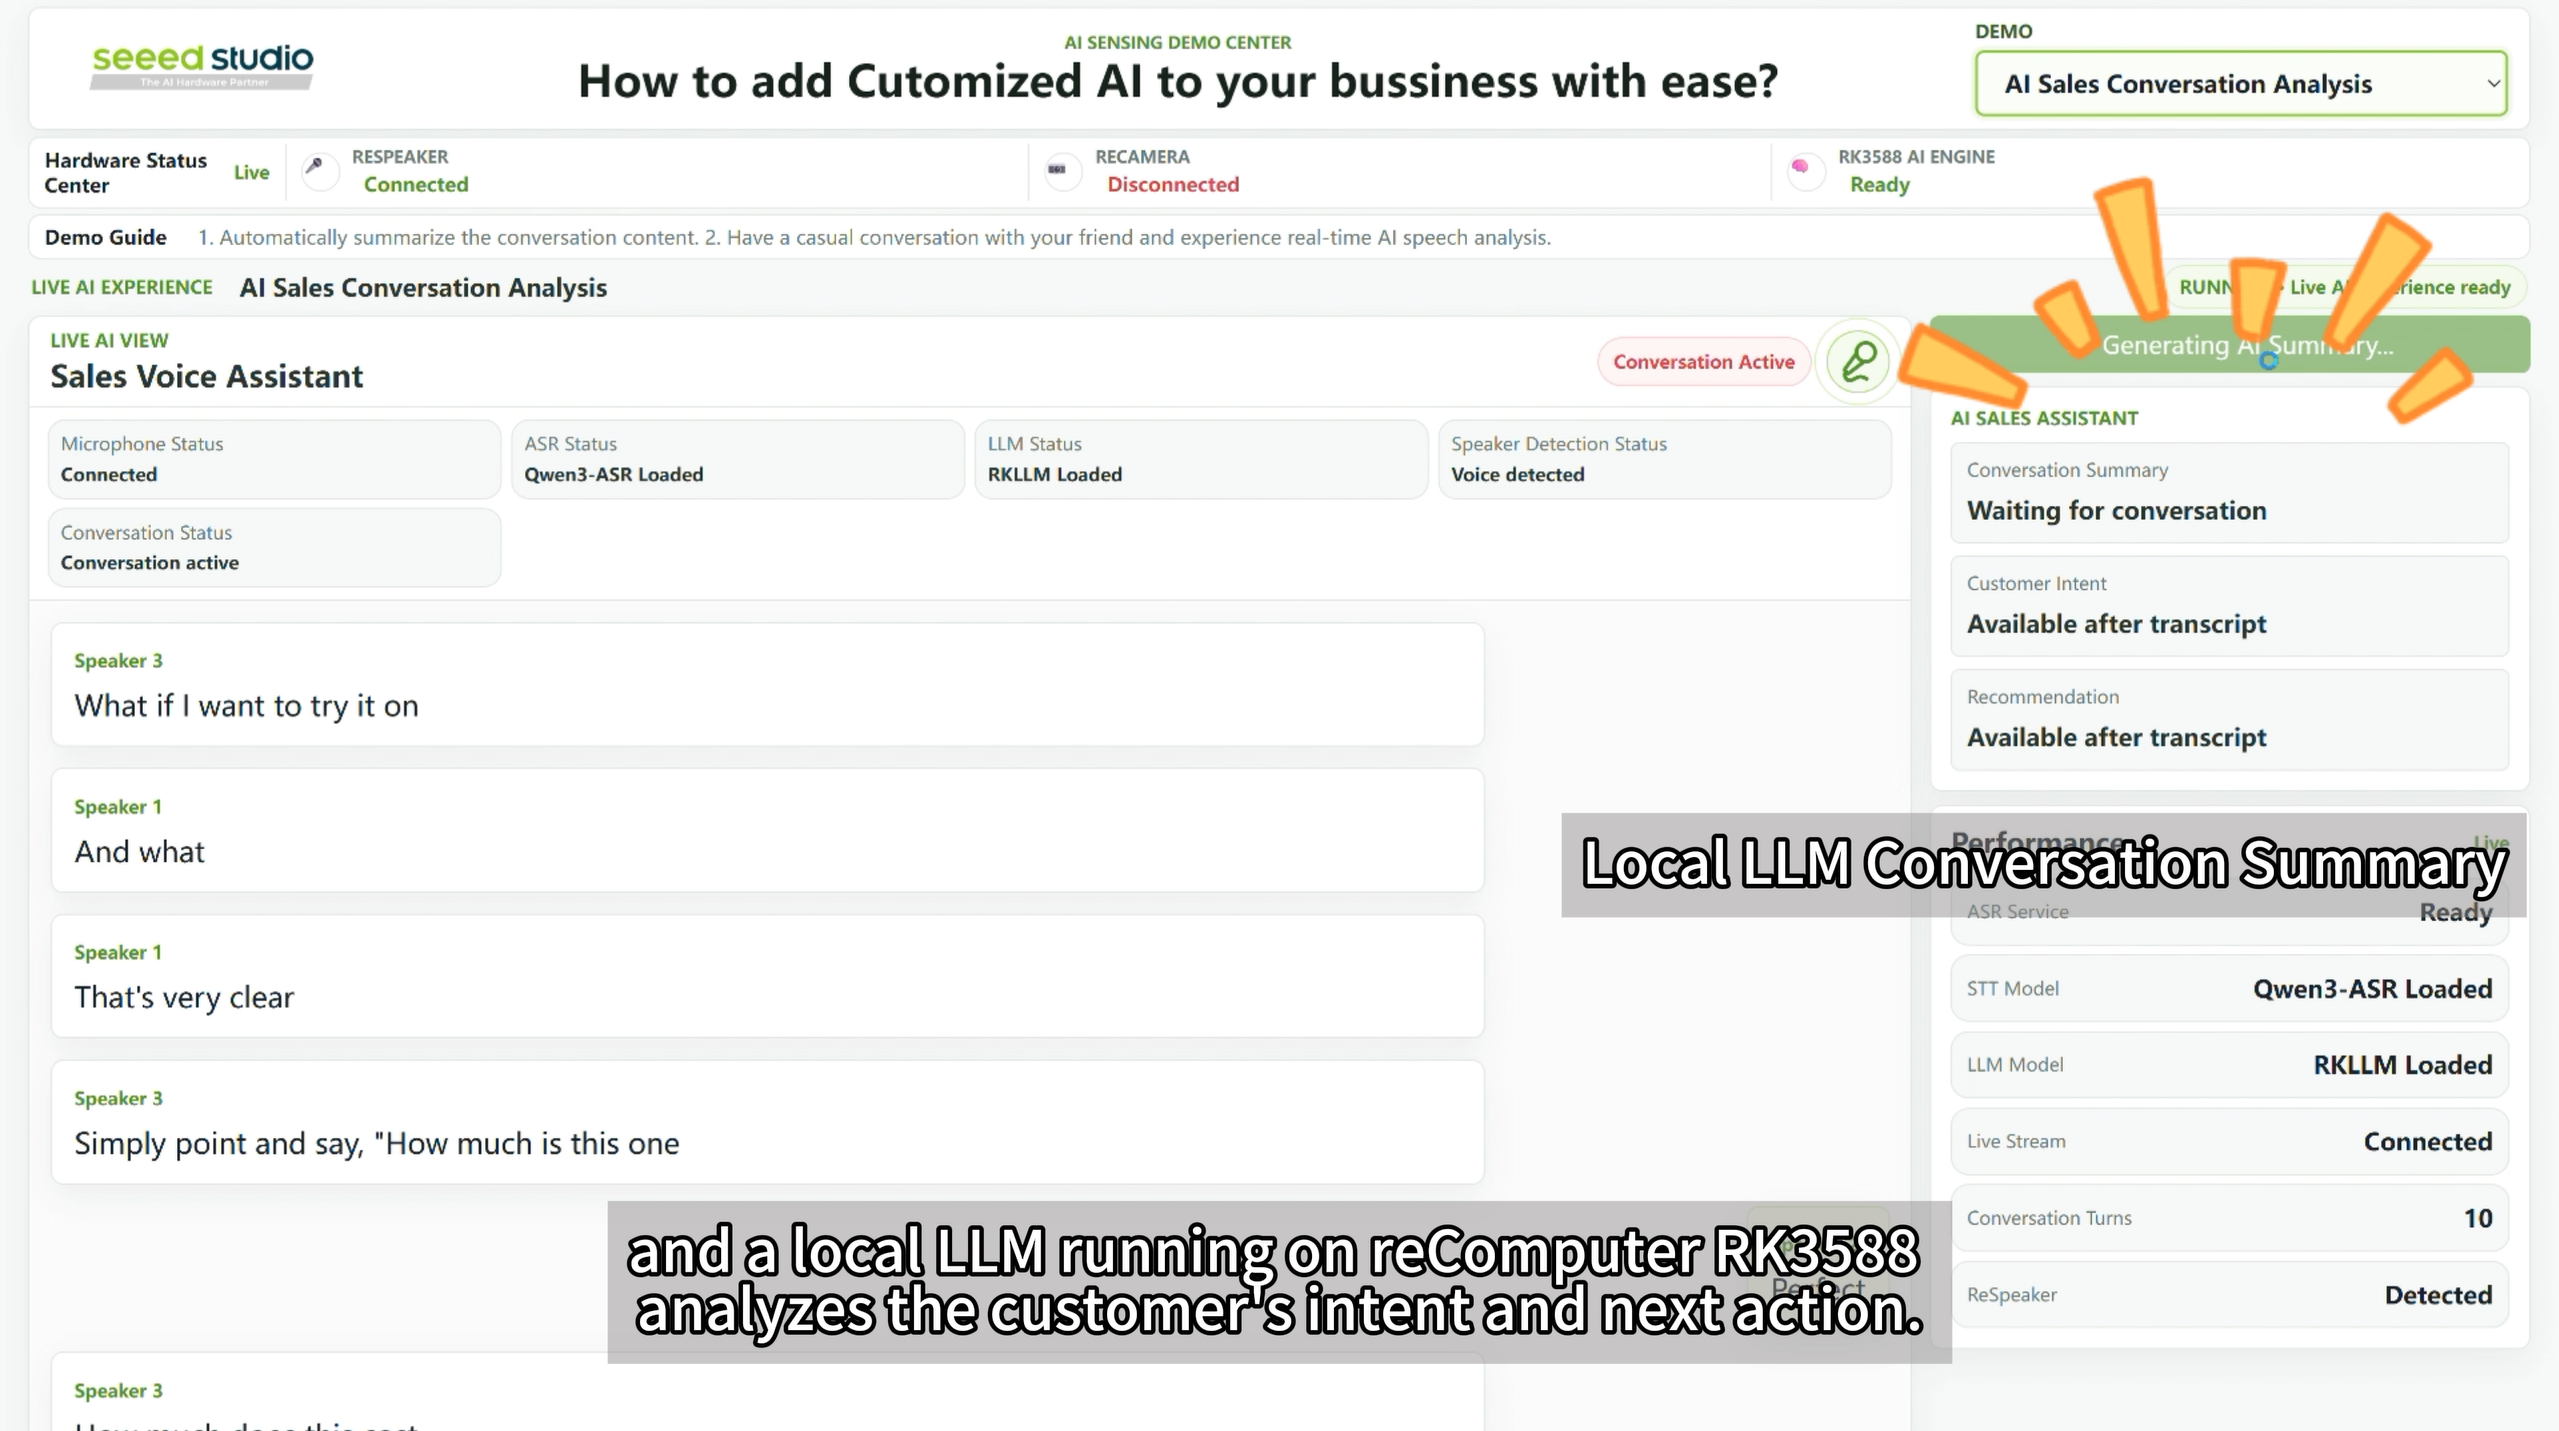
ReSpeaker XVF3800 captures the conversation and the local pipeline performs:
- speech-segment detection with Silero VAD;
- speaker embedding and separation with CAM++;
- real-time transcription with Qwen3-ASR; and
- conversation summaries, customer intent, and recommended next actions with RKLLM.
Transcripts and analysis results stream continuously to the browser. Overlapping speech is not separated, so accuracy can decrease when multiple people speak at the same time.
System architecture
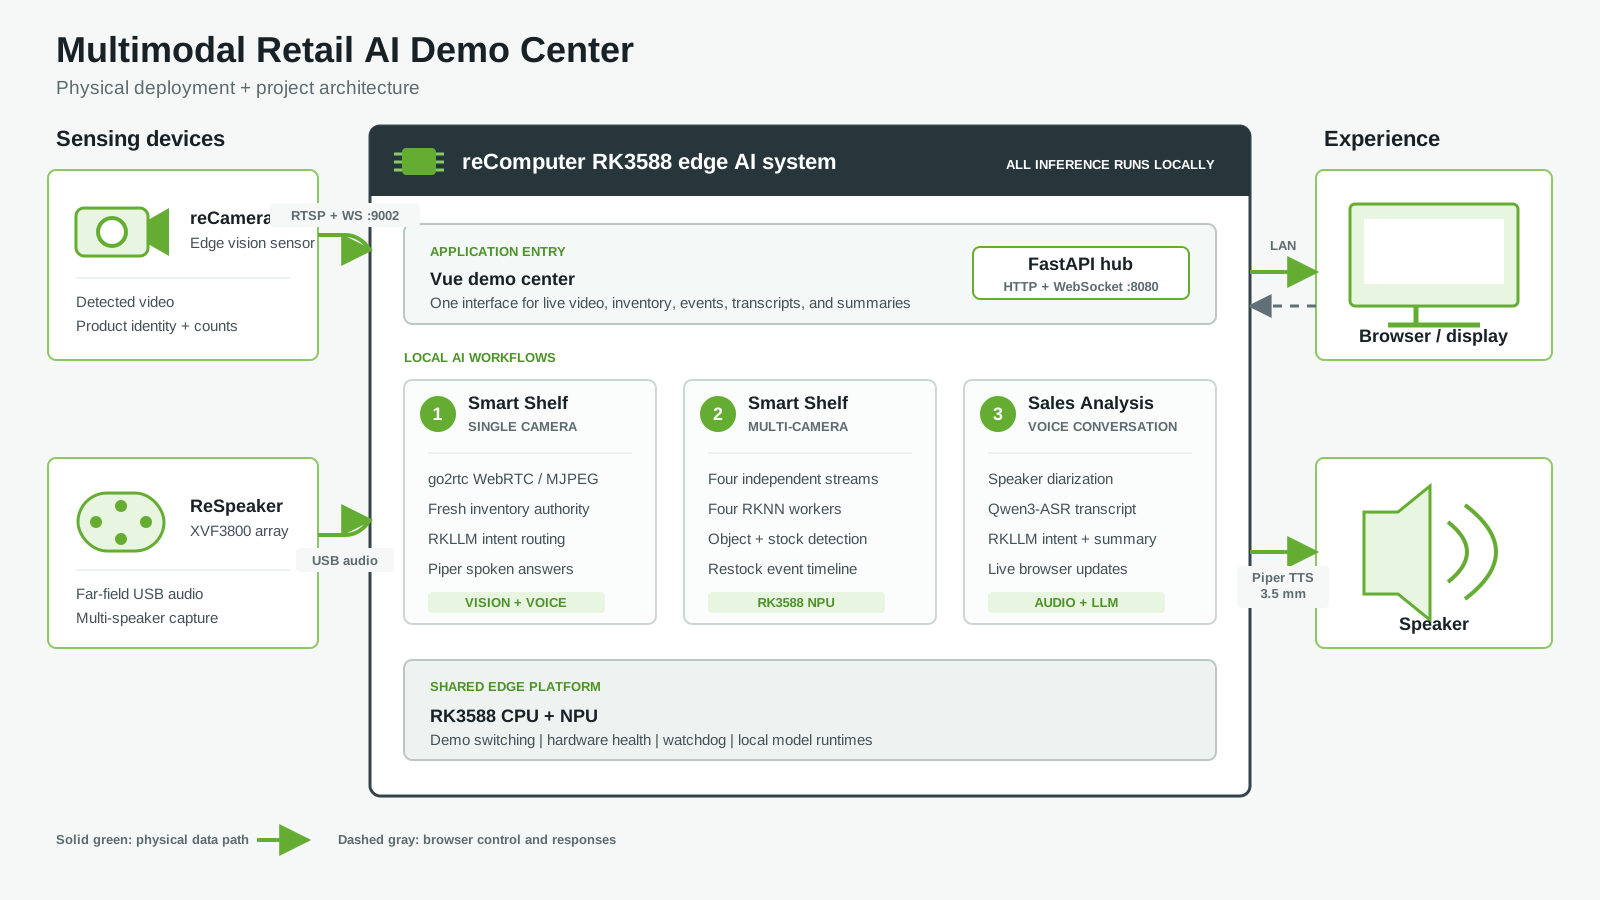
| Component | Default connection | Purpose |
|---|---|---|
| Browser → reComputer | http://<RK3588-IP>:8080 | Unified UI, REST API, and WebSocket events |
| reCamera → reComputer | RTSP :8554, WebSocket :9002 | Detected video and product state |
| ReSpeaker → reComputer | USB Audio, ALSA card containing Array | Far-field audio capture |
| reComputer → speaker | ES8311 3.5 mm output | Piper speech playback |
| Local ASR / RKLLM | :8621 / :8001 | Recognition, intent, and summaries |
Hardware requirements
| Hardware | Requirement |
|---|---|
| Edge computer | reComputer RK3588, at least 8 GB recommended |
| Camera | reCamera reachable through USB networking or Ethernet |
| Microphone | ReSpeaker XVF3800 USB microphone array |
| Audio output | Headphones or an amplified speaker on the ES8311 3.5 mm output |
| Storage | At least 12 GB for the complete offline voice assets |
| Operator display | Local browser or another device on the same LAN |
When evaluating only the four-stream shelf demo, reCamera, ReSpeaker, and the voice services can be omitted.
Software requirements
- Debian 12 arm64
- A working RKNPU driver and RKNN Runtime
- Python 3.11 and
python3-venv - Node.js 18 or newer
curlandalsa-utils- Docker and Docker Compose for ASR and RKLLM
- Optional go2rtc; MJPEG is used as the fallback
Quick start
1. Get the code
git clone https://github.com/Seeed-Projects/Lab-Prooject-RK.git
cd Lab-Prooject-RK
cp .env.example .env
Review .env, especially the reCamera address, ALSA card, audio output, and local model-service
endpoints.
2. Prepare the application
./scripts/bootstrap.sh
./scripts/verify.sh
bootstrap.sh creates the backend and RKNN environments, installs RKNN Lite, builds the Vue
frontend, and downloads checksum-pinned Piper assets. Internet access is required when those
dependencies are not already cached.
3. Optional: prepare the voice runtime
Skip this section when evaluating only the multi-camera shelf demo. The inventory assistant and sales-conversation analysis require additional ASR and RKLLM assets.
Place the separately distributed offline bundle in:
services/voice-pipeline/deploy/bundle/Then run:
cd services/voice-pipeline
./deploy/restore.sh ./deploy/bundle
docker compose -f deploy/docker-compose.asr-realtime.yml up -d
docker compose -f deploy/docker-compose.llm-summary.yml up -d
./bootstrap.sh
cd ../..
4. Start the Demo Center
./scripts/start.sh
./scripts/status.sh
Open http://<RK3588-IP>:8080 from a browser on the same network. Stop the service with:
./scripts/stop.shValidation and status
./scripts/verify.shUseful health checks:
curl -fsS http://127.0.0.1:8080/api/v1/health
curl -fsS http://127.0.0.1:8080/api/v1/hardware/status
curl -fsS http://127.0.0.1:8080/api/v1/showcase/status
curl -fsS http://127.0.0.1:8621/health
curl -fsS http://127.0.0.1:8001/health
Interactive API documentation is available at http://<RK3588-IP>:8080/docs.
Known limitations
- The complete voice experience requires ASR, RKLLM, and model assets that are not all stored in Git.
bootstrap.shrequires network access when dependencies are not cached.- The ROIs and some event rules in the four-stream demo are configured for the sample video.
- Inventory answers require a fresh reCamera product state and do not infer counts from video alone.
- Speaker separation does not support overlapping speech.
- The UI and WebSocket services do not provide public-network authentication. Use them on a trusted LAN or behind a secured reverse proxy.
Resources
The original integration code is licensed under Apache-2.0. Models, sample media, vendor wheels, and upstream services retain their own terms.